AI Audiobook to Video

| SceneMixer at a glance | What you get |
|---|---|
| Video price | From $0.06 a second (10 credits) on the default tier, up to $0.47 a second on the top tier; every price is shown before you press the button |
| Clip length | Up to 30 seconds per generated segment; an episode is composited from its segments at 1 credit a second |
| One episode, worked out | A 60-second episode on the default tier is about 660 credits (video plus compositing), about $4.11 at the lowest credit price; a 10-episode series of 90-second episodes from a 30,000-character novel is about 10,026 credits, about $62 |
| Dialogue | Spoken in the video itself, one voice per character, in any of 15 languages |
| Formats | 9:16 vertical or 16:9 landscape; 480P to 1080P, plus a 2K tier |
| Free to start | 50 credits on signup, 15 free setup images, a free storyboard for the first episode and a free 5-second video preview |
| Who uses it | 2,900+ creators have generated with SceneMixer (accounts with at least one generation, counted November 2026) |
| Input | A script, a novel or a one-line idea; .txt, .docx and .md uploads |
From a recording to a video
- Get the text. Use the book's manuscript, or a transcript of your recording from a speech-to-text tool.
- Tidy it into scenes. Cut ads, intros and housekeeping; keep the story and the narrator's best lines.
- Upload as .txt, .docx or .md. Read the cast and places.
- Choose the look and voices. Narration becomes voice-over; characters get their own voices.
- Render and join. Priced by the finished second.
Podcast episode into a drama · Which files work.
What changes from the audio
| Your audio | The video |
|---|---|
| A narrator reading | Voice-over lines, in a generated voice |
| Different voices for characters | A voice per character, chosen or matched |
| Sound effects and music | Ambience and a score generated for the episode |
| Pauses and pacing | Set by the storyboard's shot seconds |
If your own voice matters, members can upload a voice sample for a character. Picking voices.
Rights and cost
Use text you wrote or have the rights to. Reading is 4 credits per 1,000 characters; video is 10 credits a second on the default tier plus 1 credit a second to join. Novel to video · Book to movie.
Languages
Native dialogue in 15 languages
Every series below was produced by the same pipeline with the cast speaking that language natively: the interface, the working documents and the spoken lines are all in one language, and nothing is dubbed. Open one to hear it.
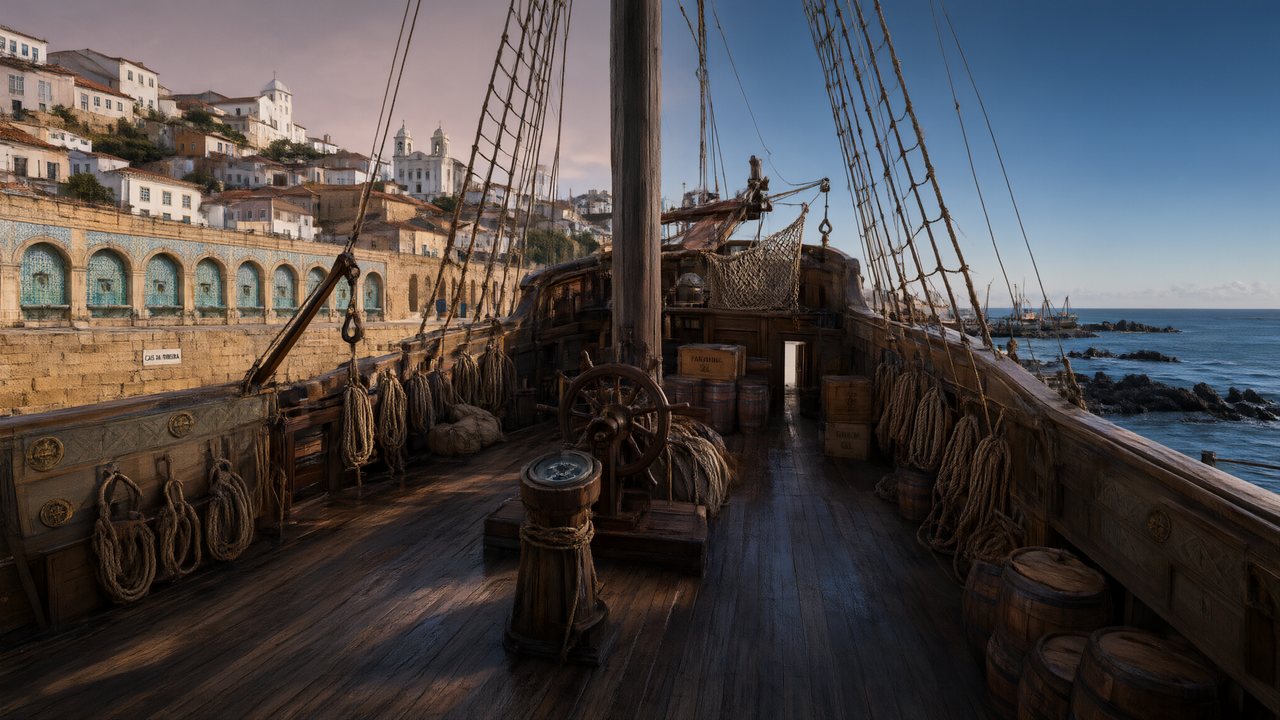 A Carta de LisboaPortuguêsNative dialogue
 윈터 프라미스한국어Native dialogue
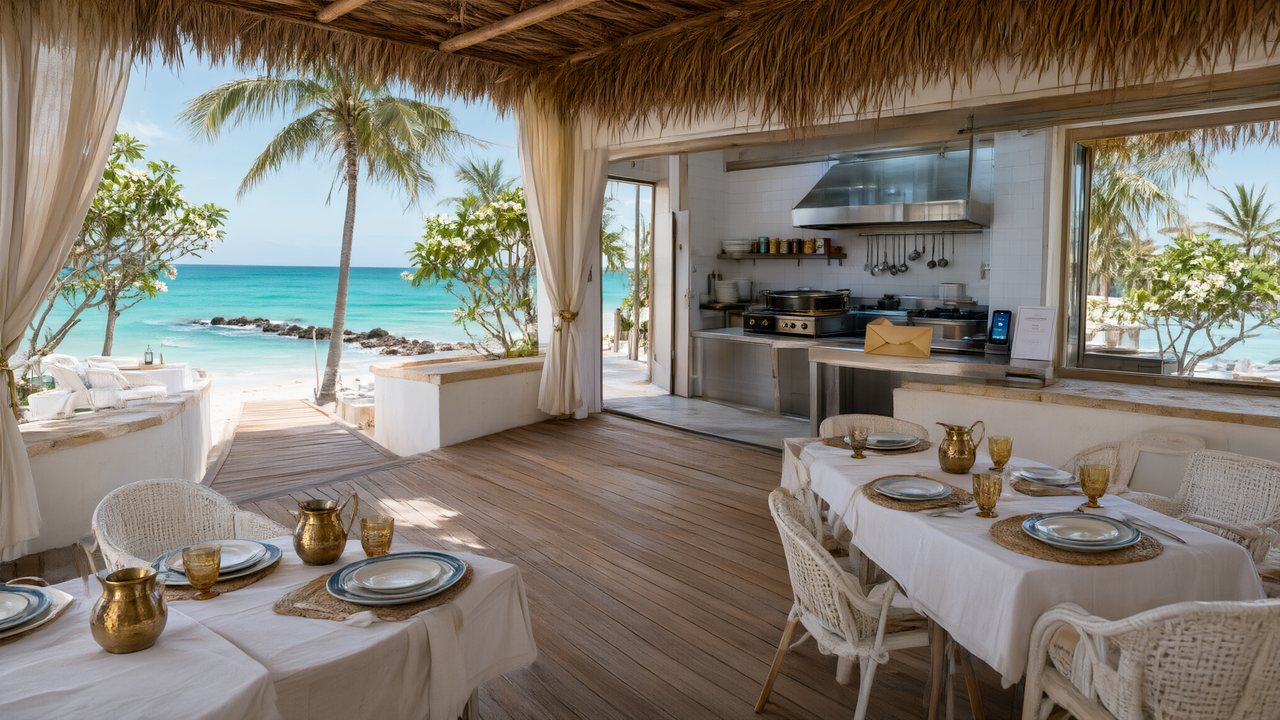 El Secreto de CostaEspañolNative dialogue
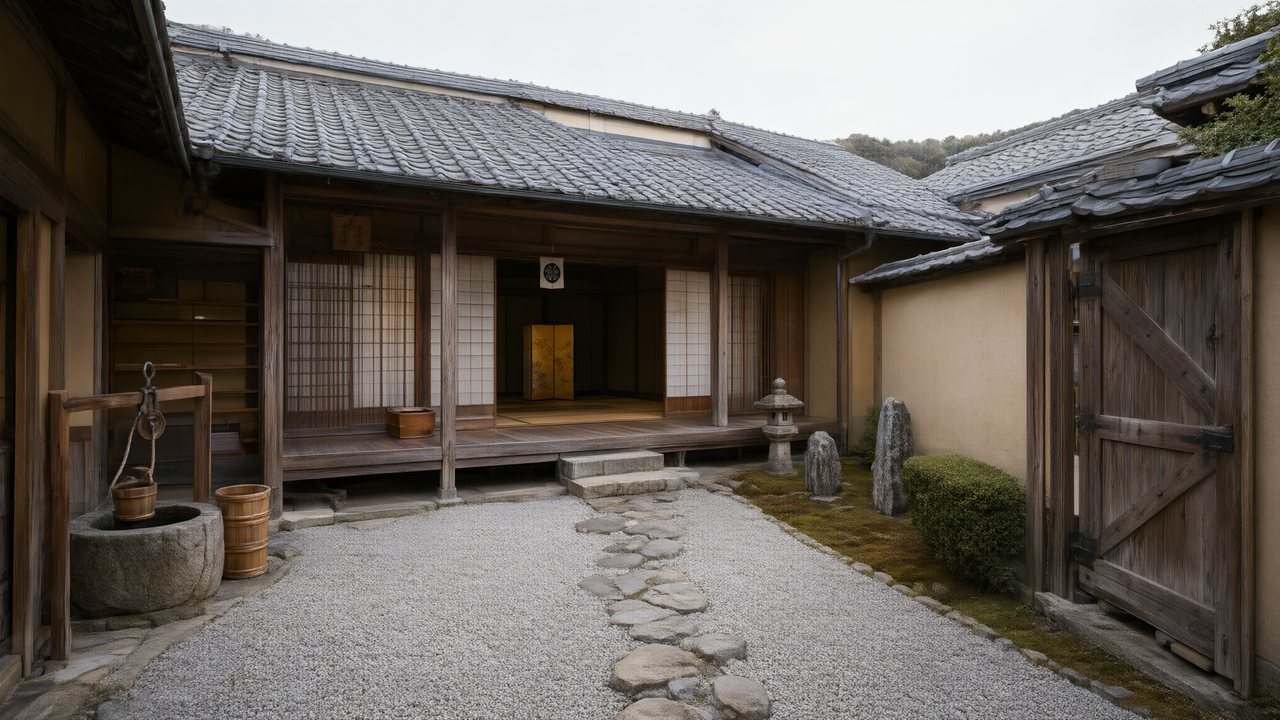 浪人の誓い日本語Native dialogue
 Ikrar JakartaBahasa IndonesiaNative dialogue
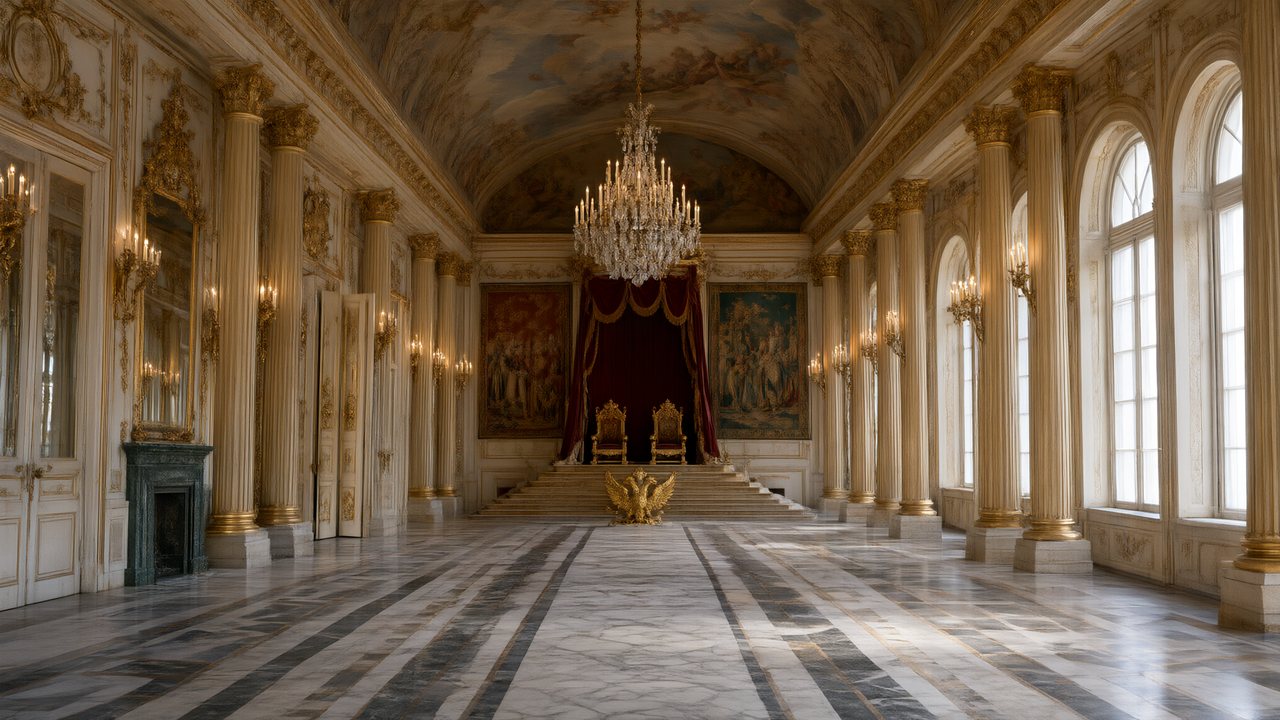 Зимняя коронаРусскийNative dialogue
 L’Héritier du DéfiléFrançaisNative dialogue
 Il Tavolo dell'OlivaItalianoNative dialogue
 De Vuurtoren van de FjordNederlandsNative dialogue
 العهد الصحراويالعربيةNative dialogue
 Çantasındaki SözleşmeTürkçeNative dialogue
 Die Istanbul-TäuschungDeutschNative dialogue
 Останній сигналУкраїнськаNative dialogue
 問劍青雲繁體中文Native dialogue
 The Last EnvelopeEnglishIn your language
In SceneMixer vs. stitching tools together
Most AI drama workflows are five or six tools in a row. This is where each step happens here, and what it replaces.
| Step | In SceneMixer | Doing it by hand with separate tools |
|---|---|---|
| Script and episode plan | Paste a script or a novel, or type one line: it is read into a cast, locations, props and an episode outline you can edit | A chat model writes the script; you split it into episodes and carry the text from tool to tool |
| Character faces and places | Every character, location and prop is drawn once as a reference sheet and attached to every shot it appears in | An image model, one sheet at a time; you upload the right reference to every clip yourself |
| Shots | A storyboard per episode with numbered shots and seconds; video is generated segment by segment in 9:16 or 16:9 against the same sheets | A video model, one clip per prompt, describing the same people again each time |
| Voices and dialogue | Lines are performed in the video itself, one voice per character, in any of 15 languages | A text-to-speech tool for each line, then a lip-sync pass on every clip |
| Fixing one shot | Edit that shot's text and regenerate the segment alone; the rest of the episode is untouched | Regenerate the clip, then re-cut the timeline |
| Finishing | Segments are composited into one episode file with its score; members download without the AI badge | A video editor to join the clips, add music and captions, then export |
| Publishing | You upload the finished episode to TikTok, YouTube, Instagram or anywhere else; nothing is posted for you | Upload by hand, the same as here |
FAQ
Can I upload an audiobook?
No. SceneMixer takes text, up to four photos for an ad, or a video to remake. An audiobook goes in as its text.
How do I get the text?
Use the manuscript, or transcribe the recording with a speech-to-text tool and tidy it.
Will it use my narration?
No. The narrator becomes generated voice-over lines; members can upload a voice sample for a character.
Can it add sound effects?
Ambience and a score are generated for the episode.
Which files can I upload?
.txt, .docx and .md.
How much does it cost?
Reading is 4 credits per 1,000 characters; video is 10 credits a second on the default tier.
Is it free to try?
New accounts start with 50 credits, with the first storyboard and a 5-second preview free.
Updated November 2, 2026